Start with a business scenario and a bounded test
Select scenarios that matter to the organisation: a privileged identity change, an unusual sign-in, a suspicious mailbox rule or a critical endpoint alert. Identify the affected service, expected event sources and people responsible for decisions. MITRE ATT&CK can provide a common vocabulary for adversary behaviour, but a technique label alone does not establish detection coverage.
Agree written scope, test accounts, permitted actions, timing, stop conditions and cleanup. Prefer controlled events or approved simulations that avoid changing real customer data. Record what the exercise will not test, such as a disconnected location or unsupported application. Choose whether analysts know the timing; a scheduled engineering check and a partially unannounced readiness exercise answer different questions.
Verify the telemetry before judging the detection
Record when the test event occurred, its source identifier and the expected attributes. Follow it through collection, transport, parsing and storage. Check event time versus ingestion time, timezone handling, identity mapping and required fields. A rule cannot reliably evaluate an event that never arrives or loses its meaningful fields during normalisation.
Test source health separately from individual detection logic. An apparently quiet system may have a disconnected collector, expired integration credential or changed audit configuration. Define how missing telemetry is detected and who restores it. Retention and access should support the agreed investigation window without collecting sensitive payloads simply because storage is available.
Measure the complete detection and triage chain
Keep distinct timestamps for event generation, ingestion, alert creation, analyst review, escalation and authorised action. State which clock starts each measure and how out-of-hours periods are treated. Comparing one provider’s ingestion-to-alert time with another provider’s event-to-response time produces a misleading service comparison.
Assess whether the analyst had enough context to make the right decision: asset importance, identity role, related events and known maintenance activity. Preserve the alert and case record as evidence. A successful alert is only one result; incorrect severity, missing context or a closed case without an accountable escalation can still expose a material operational gap.
Make response authority explicit
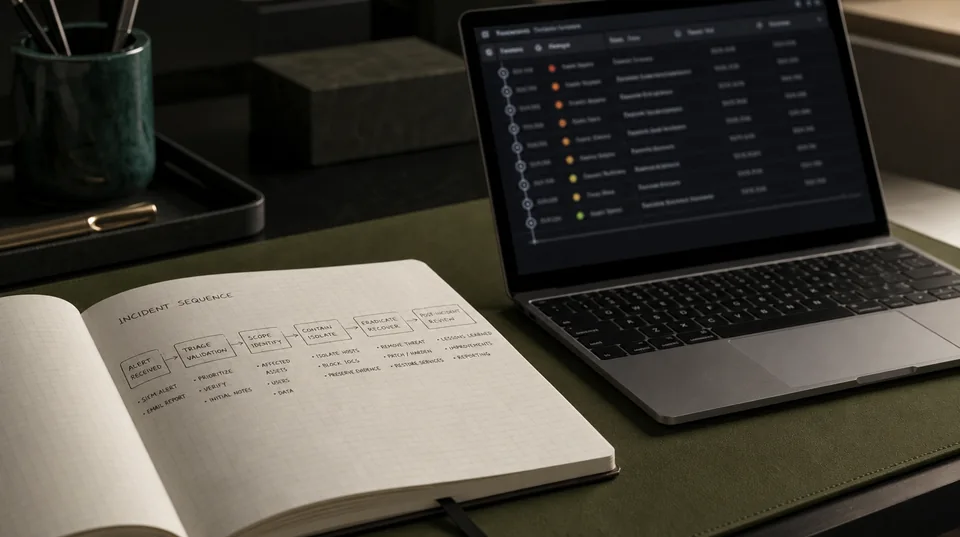
For each response action, specify the authorised decision-maker and operational dependencies. Disabling an identity, isolating a workstation and blocking a network destination have different business effects. Document which actions a provider can take directly, which require approval and how an unavailable approver is handled. Include a usable contact path for critical incidents.
Exercise escalation without assuming that a notification was received or understood. Confirm acknowledgement, transfer of essential evidence and responsibility for the next step. Where containment is tested, verify the actual outcome and an appropriate restoration path. A playbook that names an action without sufficient access or permission is incomplete.
Describe coverage with its conditions
Report each scenario as tested successfully, tested with a gap, inconclusive or not tested, with the environment and configuration recorded. Describe the observed failure point and supporting evidence. Avoid converting a small scenario set into an unsupported percentage of total protection. Passing one identity test does not establish coverage across every tenant, endpoint or attack variation.
Prioritise fixes by consequence and exposure. Assign an owner and retest the failed stage after remediation, then repeat the end-to-end scenario when the dependency could affect later stages. Preserve comparable evidence across tests. Revalidate after material changes to log sources, detection content, integrations, staffing or response permissions.
Turn findings into a service acceptance decision
A useful acceptance pack combines scope, scenario catalogue, telemetry map, time measurements, case evidence, escalation outcomes and an exception register. Management should see which business scenarios have supporting evidence, which remain uncertain and what decision or investment closes each gap. Targets must be distinguished from measured results.
TRUST-IT can help organisations assess an existing monitoring arrangement or define acceptance criteria for a new SOC or MDR service. The work connects technical detection to operational responsibility, with a prioritised remediation plan and reproducible retests. Its value is a defensible understanding of what the service can observe and act on within the agreed scope.
Further reading
Put the guidance to work
Bring security signals together, investigate suspicious activity, and define a response process your team can act on.
Security operations & MDR